
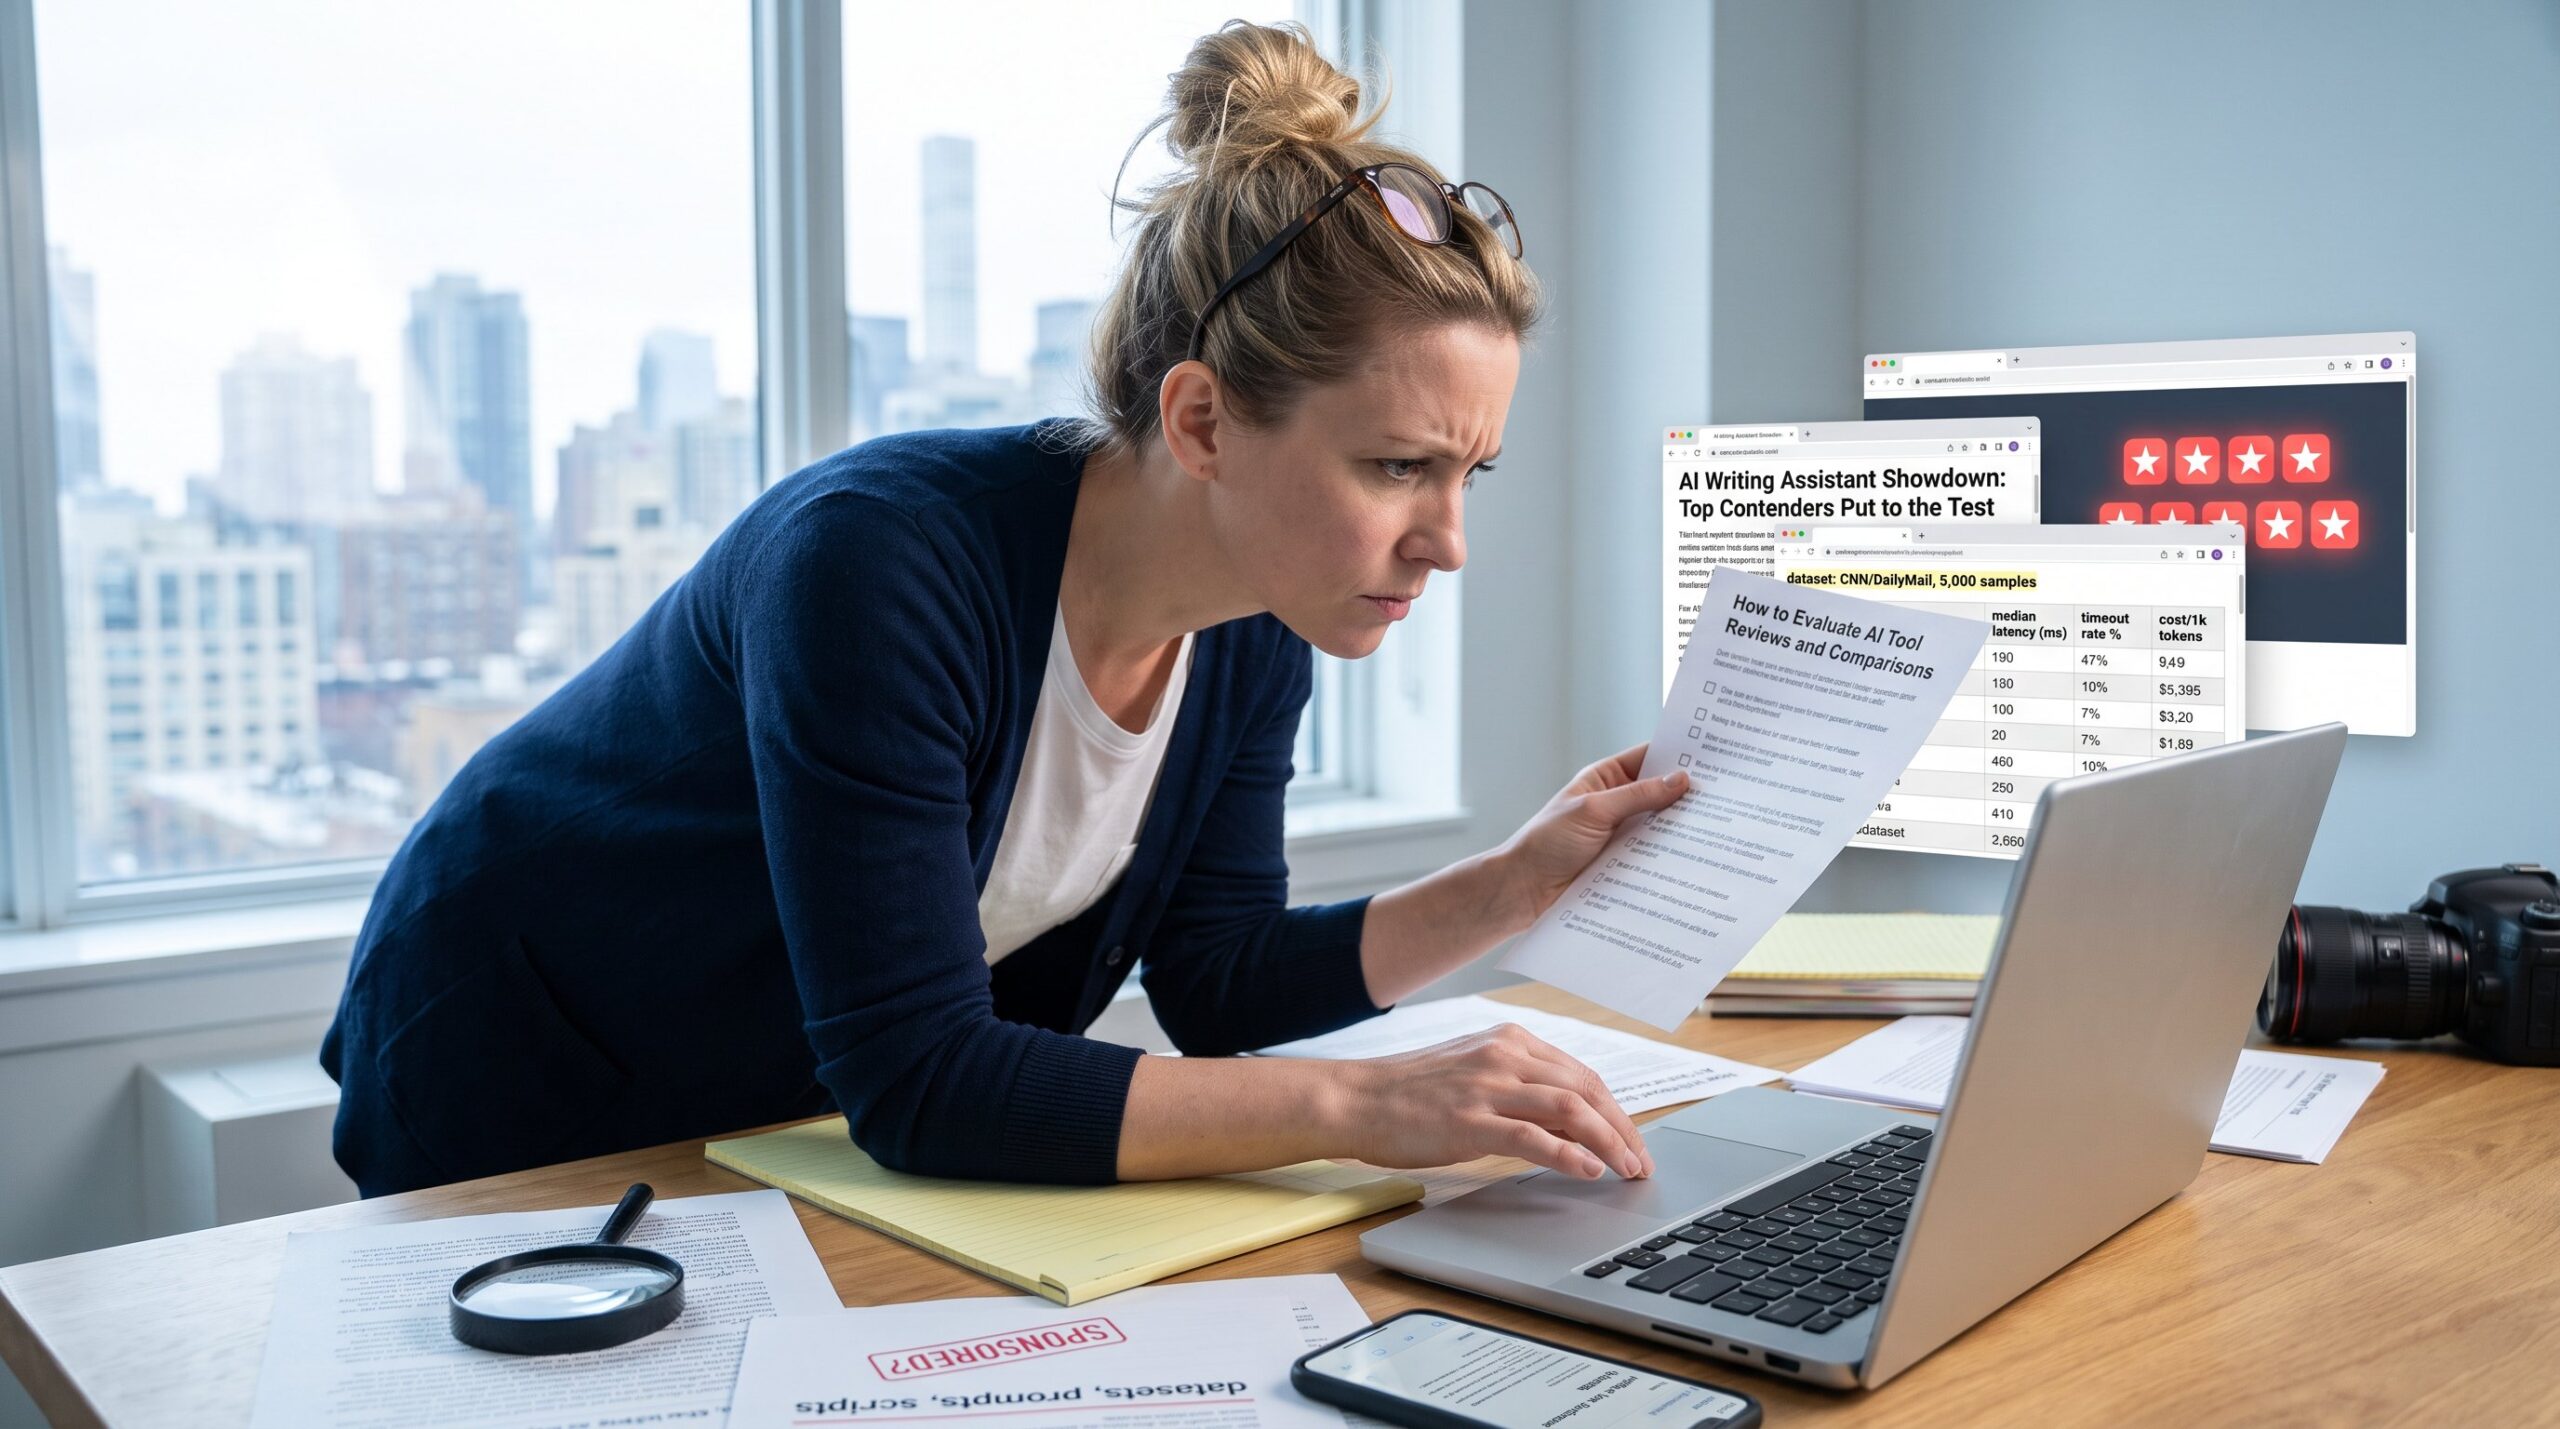
How to evaluate AI tool reviews and comparisons starts with spotting what a reviewer actually tested, who paid for it, and whether the results map to real use cases. Readers often trust ratings but get burned by vendor‑run benchmarks, recycled marketing text, and missing failure modes. This guide gives concrete signals to separate careful, reproducible reviews from puff pieces. It shows what numbers mean, which disclosures matter, and a short, actionable checklist readers can use before signing up or buying. Expect clear steps, red flags, and small experiments to confirm claims.
Key Takeaways
- Evaluating AI tool reviews effectively requires checking reviewer independence, disclosed funding, and clear test methodologies including datasets and prompts.
- Beware of reviews that use vendor-provided scores without transparent data, lack failure examples, or show suspicious rating patterns indicating potential manipulation.
- Trustworthy reviews provide detailed performance metrics such as latency, failure rates, and costs at scale rather than vague claims like “fast” or “best.”
- Look for reproducibility in reviews, confirmed by named datasets, test scripts, and cross-validation from independent sources.
- Before purchasing, run small experiments with your own data to validate claims, exposing hidden costs and real-world failure modes.
- Use AI tool reviews in context with broader technology trend coverage to make well-informed decisions aligned with your needs.
Why AI Reviews And Comparisons Often Mislead — Red Flags To Watch For
Red flag: the review lists scores but hides how tests were run. Independent reviewers show dataset names, scripts, and test prompts. Misleading pieces often use vendor‑supplied numbers without datasets, which inflates performance in narrow conditions.
Vendor funding and undisclosed incentives are common. A review that never mentions sponsorship, affiliate links, or free hardware is suspect: independent disclosure is a basic credibility signal. Another pattern is generic praise: four paragraphs of buzzwords and no failure cases. Honest reviews include at least one clear example where the tool failed and why.
Watch user reviews for suspicious bursts. Sudden spikes of five‑star ratings and many single‑review accounts are reliable signals of manipulation. Also note whether the reviewer tested the product with real inputs. Reviews that only show vendor demo prompts usually overstate accuracy.
Practical warning: if a review offers only high‑level claims like “fast” or “best,” demand numbers, latency in ms, failure rate percentages, or token costs at scale. For instance, a trustworthy note might say “serves 10,000 requests/day with median latency 220 ms and 0.7% timeout rate.”
Context links: FeedBuzzard’s coverage of emerging tools helps place reviews in a broader trend: readers can compare evaluations with the site’s technology primer on trends and wearables. Another useful read compares AI with human choices on decision workflows at tools, human, decision.
Core Evaluation Criteria For Trustworthy AI Tool Reviews
Trustworthy reviews state independence, method, and scope up front. The single clearest fact: a review becomes useful when the reviewer names datasets, scripts, and the exact prompts used. Without that, numbers are directional at best.
Key criteria:
- Independence and conflicts: who benefits if the tool looks good?
- Reproducible methodology: datasets, test scripts, and environment details.
- Performance dimensions: quality, reliability, security, documentation, and predictable pricing.
- Cross‑validation: are the same claims repeated by independent sources?
Examples help. A solid review will say, “we evaluated summarization on CNN/DailyMail, used 5,000 items, and measured ROUGE‑1, median latency, and cost per 1,000 tokens.” That level of detail lets another team reproduce the claim.
Readers should also check for practical trade‑offs. Does the reviewer measure failure modes like hallucination rate or unsafe content? Does it provide a cost projection at 100k/users or 1M tokens per month? Reviews that omit cost at scale or failure statistics often target novices.
Related pieces on the site add context: explorations of app builders to watch and deep dives into AI agents provide examples of methodology used in the field.
Conclusion
Trustworthy AI reviews combine clear incentives, reproducible testing, and honest failure analysis. Readers gain the most value by treating numbers as directional, checking funding and methods, and running a quick pilot with their own data. These steps reduce surprise, reveal hidden costs, and help pick tools that truly fit the task. For ongoing context and trend tracking, readers can consult FeedBuzzard’s broader technology coverage to compare tool claims with sector patterns.